How the council works
A single model is one voice with one set of blind spots. The council turns that into a panel: ask once, get answers from up to four different engines in parallel, then have a chair read all of them and write one decisive verdict — with the disagreement called out, because that’s usually where your real decision lives.
The panelists
Section titled “The panelists”| Panelist | CLI | Notes |
|---|---|---|
| Claude | claude | Claude Code |
| Codex | codex | OpenAI Codex |
| Antigravity | agy | Google’s Antigravity CLI |
| Ollama | ollama | Local models at localhost:11434 |
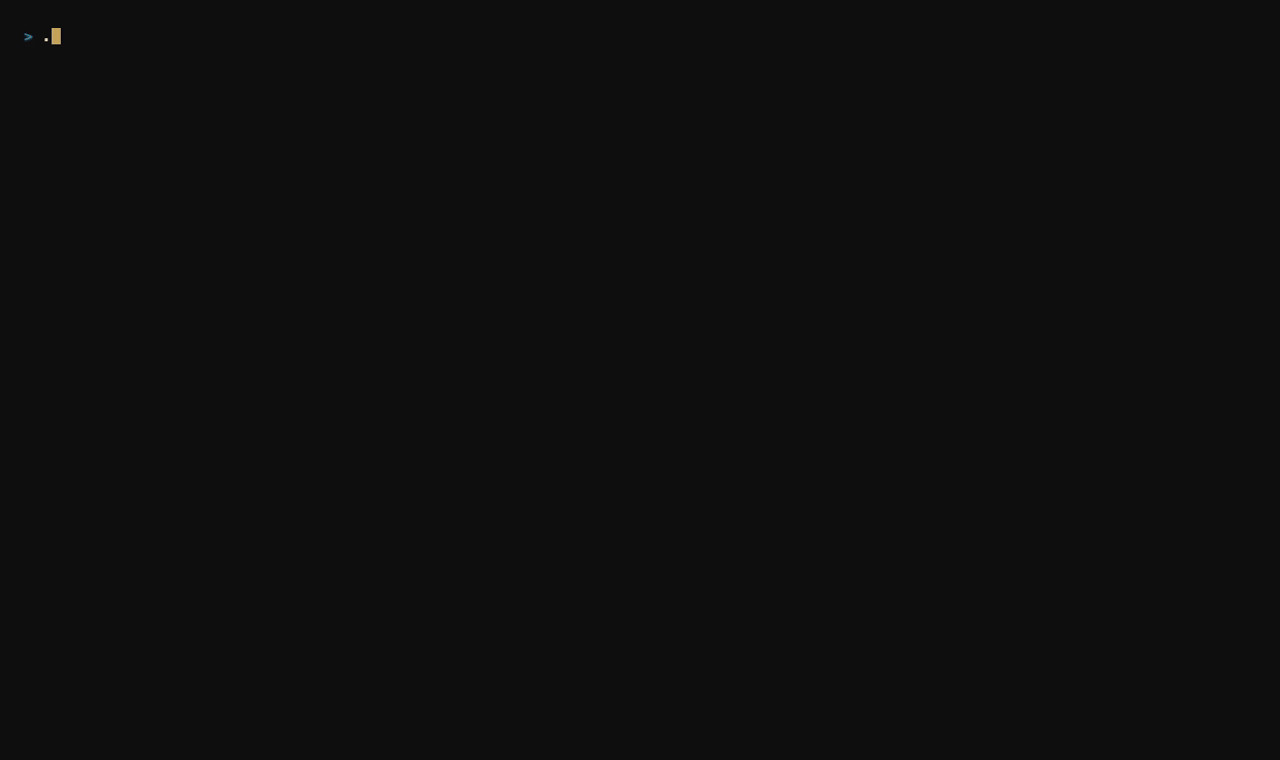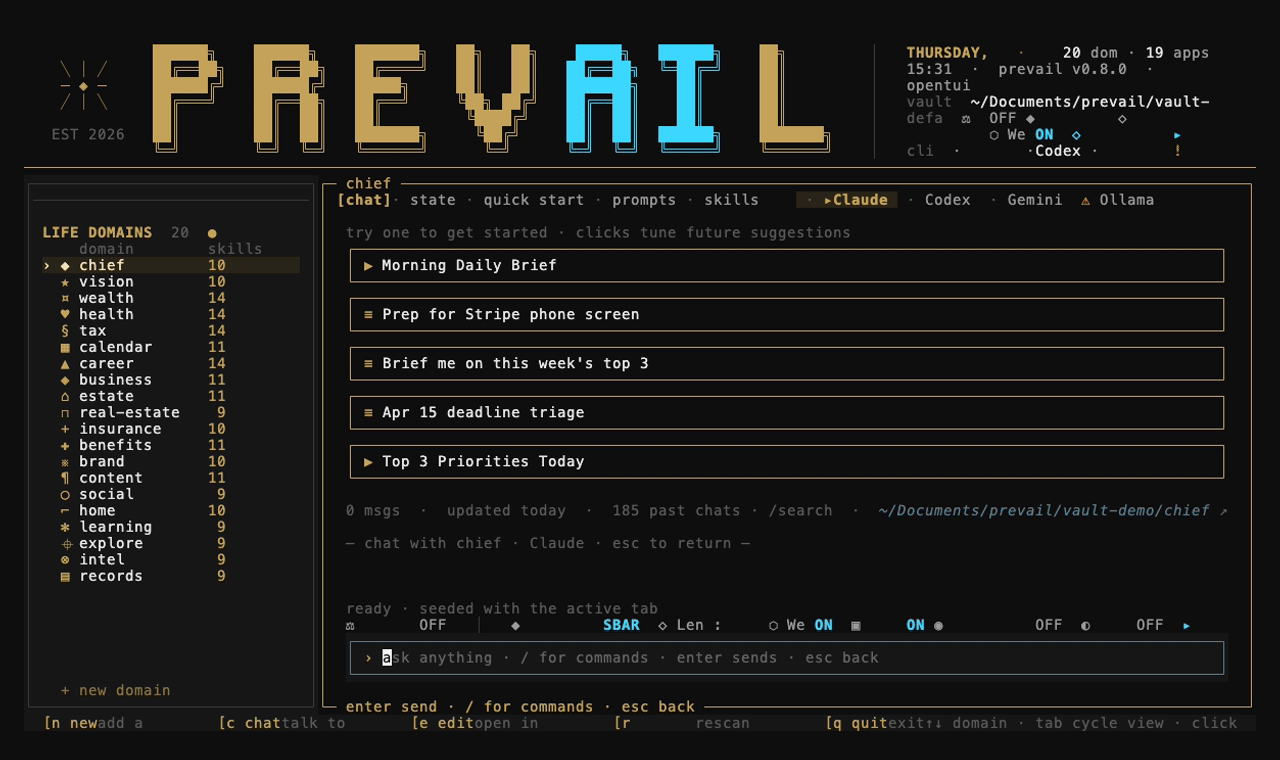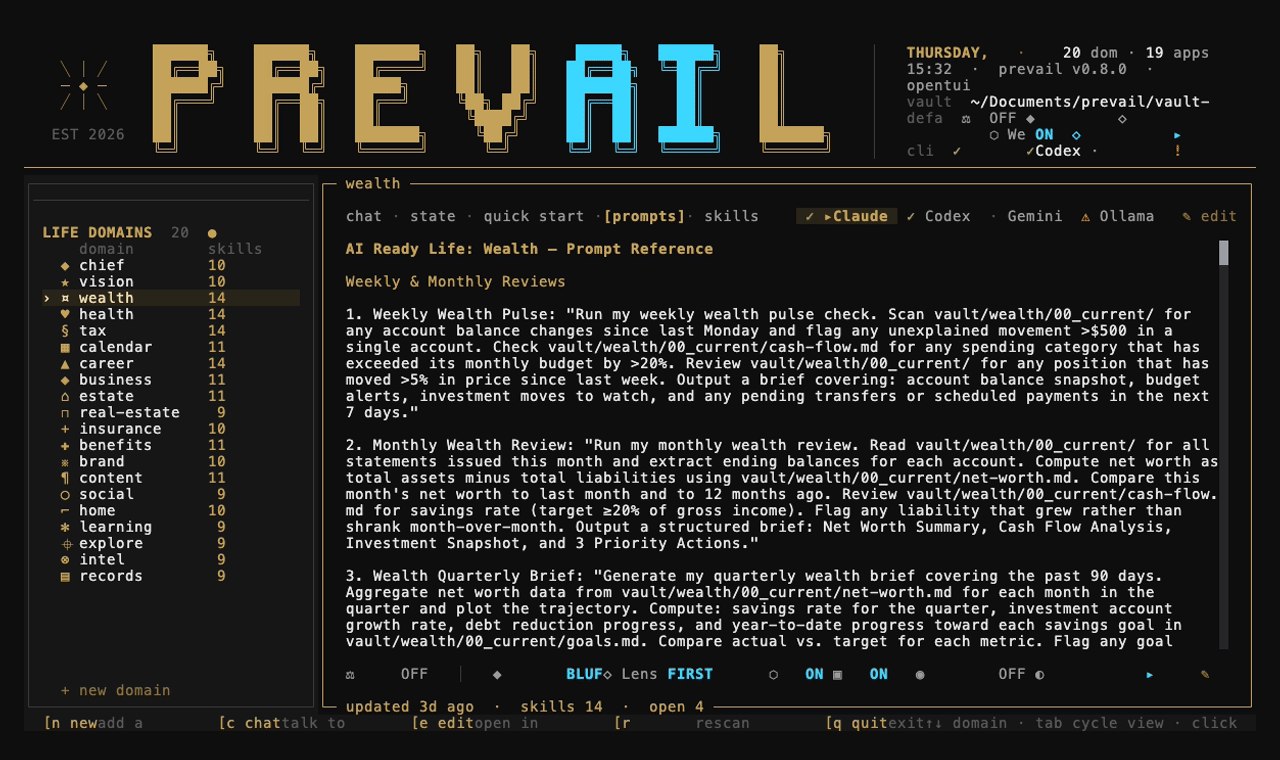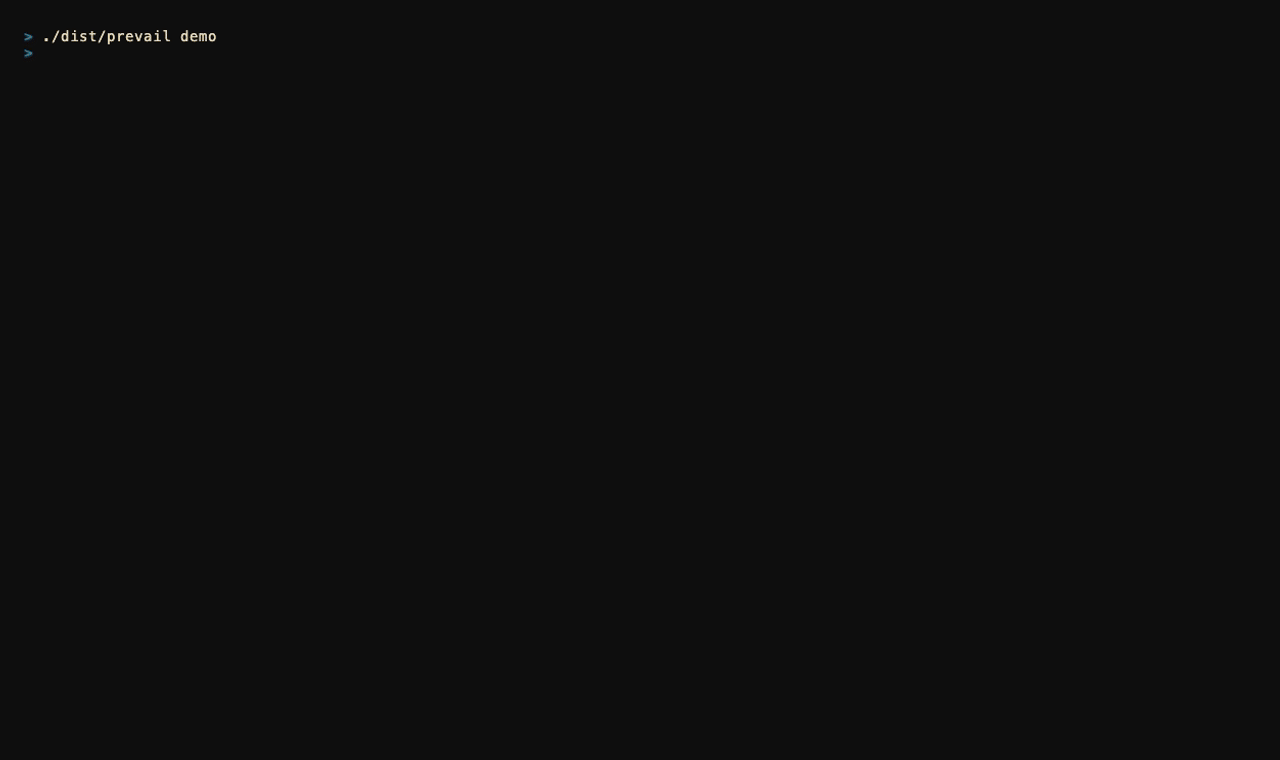
Prevail auto-detects which are installed and logged in. The council uses whichever are available — you don’t need all four. Run a sensitive domain on Ollama alone and nothing leaves your machine.
What happens on /council
Section titled “What happens on /council”/council should I prepay the mortgage or invest the cash? │ ├─ expand panelists (each CLI, optionally × each lens) │ ├─ fan out in parallel ──▶ claude │ ──▶ codex │ ──▶ agy │ ──▶ ollama │ ├─ sanitize each reply (prevent verdict spoofing) │ ├─ chair reads all replies ──▶ synthesizes ONE verdict │ ├─ divergence panel ──▶ "where panelists disagreed" │ └─ persist: sessions DB + _log/ + _journal/- Fan out. The question goes to every panelist as a bare turn, in parallel. Replies stream in as they arrive.
- Sanitize. Each reply is cleaned so a panelist can’t spoof the final verdict (any line that starts with
##is rewritten to(panelist) ##). See Security. - Synthesize. The chair model reads all replies and writes one verdict.
- Surface divergence. A panel highlights where the panelists recommended different things or weighed risk differently.
- Persist. The turn is saved to the session DB and summarized into the vault’s logs and journal.
A real verdict
Section titled “A real verdict”┌─ wealth ─────────────────────────────────────────────────────── prevAIl ─┐│ › /council should I prepay the mortgage or invest the cash? ││ ││ ◆ convening · claude · codex · gemini · ollama ││ ││ ◇ Claude At your tax rate the effective mortgage cost is ~4.1%. ││ A diversified index has cleared 7% long-run. Math: invest. ││ ◇ Codex Spread = (after-tax return − rate) × principal × years. ││ Positive → invest. Keep 6 months liquidity floor. ││ ◇ Antigravity Behavioral: a guaranteed return on a known liability vs. ││ a probabilistic one. Pick the path you'll actually hold. ││ ◇ Ollama Local-only check: same conclusion as the cloud panel. ││ ││ ┌─ ▸ Where panelists disagreed ──────────────────────────────────┐ ││ │ Liquidity floor: Codex says 6mo, Antigravity says 12mo (risk-off). │ ││ └────────────────────────────────────────────────────────────────┘ ││ ││ ┌─ ◆ Verdict · synthesized by Claude ────────────────────────────┐ ││ │ Invest IF (a) ≥6mo liquidity, (b) you'll hold through −30%, │ ││ │ (c) spread > 2%. Else prepay. Liquidity is the binding test. │ ││ └────────────────────────────────────────────────────────────────┘ ││ ││ ready · 4 calls · 3k↑ 1.4k↓ · ~$0.03 ◆ Framework: BLUF ● ON │└──────────────────────────────────────────────────────────────────────────┘Configuring the council
Section titled “Configuring the council”/council use claude codex ollama who sits on the council/council model codex gpt-5.4 pin a model for one panelist/council chair claude opus pin who synthesizes the verdict/council config show the current setupBy default the first panelist to answer becomes the chair; pin one with /council chair and it persists across sessions in your config.
Add your own take first
Section titled “Add your own take first”/gut I lean toward prepaying — I value the guaranteed return./council mortgage or invest?/gut captures your instinct before the panel answers. The chair weighs it into the synthesis, so the verdict engages with your reasoning instead of ignoring it.
Calibrate it over time
Section titled “Calibrate it over time”The /calibration command lets you record decisions you’re confident about, building ground truth that helps you judge which panelists and chairs serve you best. Pair it with the canonical benchmark to grade every new model against your real questions.